Open Source Alternatives
  • Alternatives
  • Categories
    Categories by size882 projects
    • Developer Tools461
    • AI & Machine Learning404
    • Web Development196
    • Business & Productivity191
    • Communication & Collaboration126
    • Security & Monitoring126
    • IT Management123
    • Product & Project Management106
    • Cloud & Hosting105
    • Data & Analytics104
    Browse all 21 categoriesLLMOps & AI Tooling, Design & Creative and 9 more
  • Blog
  • Advertise
SearchNotion, Slack, password manager.../
Submit
Open Source Alternatives
  • Alternatives
    • Developer Tools461
    • AI & Machine Learning404
    • Web Development196
    • Business & Productivity191
    • Communication & Collaboration126
    • Security & Monitoring126
    • Browse all 21 categories
  • Blog
  • Advertise
Submit your project

New open source projects by email

The projects we add and every new guide. Free, unsubscribe any time.

Open Source Alternatives LogoOpen Source Alternatives

Handpicked Open Source Alternatives to Paid Softwares

Product

  • Categories
  • Tag
  • Advertise

Resources

  • Blog
  • Collection
  • Submit

Company

  • Privacy Policy
  • Terms of Service
  • Refund Policy
  • Sitemap

Alternatives

  • Claude Code
  • Jira
  • Notion
  • Slack
  • Linear
  • Wispr Flow
  • All alternatives
© 2026 Open Source Alternatives. All rights reserved.
Open SourceAlternatives
Home/Categories/AI & Machine Learning/stt
icon of stt

stt

Open source alternative to MacWhisper, HeyGen, Rask AI, Maestra and Dubverse

  • 4.8K stars
  • GPL-3.0
  • Updated this year
  • Last commit 273 days ago

Last verified Oct 14, 2026

Convert audio and video files to text offline using faster-whisper models. GPL-3.0 licensed, outputs JSON, SRT with timestamps, and plain text.

Visit websiteGitHub4.8K starsDeploy on Hostinger
image of stt
TL;DR

stt is a local, offline speech-to-text tool built on the faster-whisper model. It replaces paid cloud transcription services like Maestra and Rask AI, running entirely on your own machine with no per-minute fees and no data sent to external servers. Licensed GPL-3.0. Best for developers who need an OpenAI-compatible local Whisper endpoint and content creators generating subtitles in bulk.

Read the full breakdownHide the full breakdownWho it is for, how it works, trade-offs, the quick start and the FAQ
who it's for

Who stt is for#

Developers replacing the OpenAI Whisper API

stt exposes a /v1 endpoint that accepts the same request format as OpenAI's transcriptions API. Teams already calling Whisper in production can point their base_url at a local stt server to eliminate per-minute API costs for high-volume or offline workloads.

Skip if:

If your transcription volume is low and latency matters more than cost, the managed OpenAI API is simpler to operate. stt requires server management and CUDA setup for best performance on long audio.

Content teams generating subtitles for video archives

Upload video files to the browser UI and receive SRT subtitle files with timestamps. Supports 14 languages. No internet connection needed, making it practical for air-gapped environments or batch processing large video libraries offline.

Skip if:

If you need live real-time captioning or integrated video translation and dubbing, stt handles transcription only. pyVideoTrans (a related project by the same author) adds translation and voice synthesis on top of this.

Researchers transcribing interviews or field recordings

Offline inference means sensitive interview recordings never leave the local machine. Choose SRT output for timestamped transcripts or JSON for downstream text processing. The small or medium model provides a balance of accuracy and speed on CPU-only hardware.

Skip if:

If you need speaker diarization (identifying who is speaking when), stt does not include that feature. Whisper-based models transcribe speech but do not assign speaker labels to individual turns.

the problem

The problem it solves#

Cloud-based transcription services charge per minute or per hour, and rates scale fast when you are processing dozens of video recordings, podcast episodes, or meeting archives. Beyond cost, uploading sensitive recordings to a third-party server creates privacy exposure: you have no control over how that audio is stored, analyzed, or retained.

The only path forward is running Whisper locally, but setting up the official OpenAI Whisper library with the right Python environment, CUDA drivers, and ffmpeg dependencies is a multi-step process with version conflicts at every turn. There is no built-in web UI, no API server, and no output formatter for SRT subtitles. stt packages all of that into one deployable app.

how stt solves it

How it solves it#

Local browser-based UI

A local web server starts on port 9977 and opens automatically in your browser. Upload audio or video files by clicking the upload area or via drag-and-drop, select the source language and model size, and the transcript appears in the output box in the selected format. No command-line interaction required after launch.

Multiple output formats

Returns transcripts as SRT (with per-line timestamps), JSON, or plain text. SRT output is ready to upload directly to YouTube, Premiere Pro, or any video editor that accepts subtitle files. JSON output includes timestamp data suitable for downstream text processing pipelines.

OpenAI-compatible API endpoint

Exposes a /v1 endpoint that accepts the same request structure as OpenAI's speech transcription API. Point the base_url in your existing OpenAI client to http://127.0.0.1:9977/v1 and the rest of the integration stays unchanged. Supports text and SRT response formats.

Scalable model selection

Ships with the tiny model built in. Download base, small, medium, or large-v3 model packages from the Releases page and place the extracted folder in the models/ directory to switch. Larger models improve accuracy on accented speech and technical vocabulary; large-v3 requires an Nvidia GPU with 8GB or more VRAM.

CUDA acceleration for Nvidia GPUs

Defaults to CPU inference. Enable CUDA by editing set.ini to set devtype=cuda after installing CUDA Toolkit and cuDNN. GPU acceleration is significant on large-v3 inference and on video files over 20MB. Without CUDA configured, the large and large-v3 models will cause out-of-memory crashes.

14 supported languages via HTTP API

Supports Chinese, English, French, German, Japanese, Korean, Russian, Spanish, Thai, Italian, Portuguese, Vietnamese, Arabic, and Turkish. Language is selected per request in the browser UI or passed as the language parameter in an API call to http://127.0.0.1:9977/api.

strengths · trade-offs

Strengths and trade-offs#

Strengths

  • Fully offline: no audio leaves your machineAll inference runs locally using downloaded model weights. No audio or video is sent to any external server. This matters for recordings that contain confidential meetings, legal proceedings, or personal data subject to privacy regulations. Air-gapped deployments are fully supported.
  • Drop-in replacement for the OpenAI Whisper APIThe /v1 endpoint matches the OpenAI Whisper API format, so existing integrations need only a base_url change to switch. Unlike the OpenAI API (billed per audio minute), stt charges nothing beyond the server it runs on.
  • Faster inference via faster-whisperBuilt on faster-whisper (Systran's CTranslate2-based reimplementation), which runs Whisper models faster and with lower memory usage than the original OpenAI implementation on comparable hardware.
  • Pre-compiled Windows binary requires no PythonWindows users can download the pre-compiled release from the GitHub Releases page, extract it, and run start.exe with no Python or package management required. This removes the setup barrier for non-developers who need offline transcription.

Trade-offs

  • -Large models require an Nvidia GPU and CUDA setupThe large and large-v3 models are only practical on machines with an Nvidia GPU and at least 8GB VRAM. Running them on CPU leads to out-of-memory crashes, especially on video files over 20MB. CUDA setup requires manual driver, toolkit, and cuDNN installation, with several failure modes and DLL dependency issues documented in the README.
  • -Chinese output may produce Traditional instead of Simplified charactersThe README notes that Chinese speech recognition sometimes outputs Traditional Chinese characters rather than Simplified. This is a known behavior of the underlying faster-whisper model and is not configurable from within stt.
  • -GPL-3.0 restricts proprietary commercial distributionGPL-3.0 requires that any software you distribute that incorporates stt must also be licensed under GPL-3.0 with source code made available. This is fine for internal use or open source projects, but rules out embedding stt in a proprietary commercial product you distribute.
versus alternatives

stt vs alternatives#

stt vs Maestra

Maestra is a cloud-based AI transcription and subtitle tool that supports automatic speech recognition, subtitle generation, and dubbing across multiple languages. stt covers the transcription and SRT generation portion of that feature set, running offline on your own machine rather than sending files to a cloud service.

FeaturesttMaestra
LicenseGPL-3.0Proprietary
Self-hostingYesNo
Offline useYesNo
TranscriptionYesYes
SRT subtitle outputYesYes
Video dubbingNoYes
PricingFree (self-hosted)Paid subscription

stt is the better choice when your recordings contain sensitive content that cannot leave your network, when you are processing high volumes of audio where per-minute cloud pricing compounds, or when you need an OpenAI-compatible local endpoint for an existing codebase. Maestra is the better choice when you need a full workflow including video dubbing, translation, and a polished cloud editor with team collaboration.

stt vs Rask AI

Rask AI focuses on video dubbing and translation: you upload a video, and Rask translates the script and replaces the original audio with synthesized speech in the target language. stt handles only the transcription step, not translation or voice synthesis.

FeaturesttRask AI
LicenseGPL-3.0Proprietary
Self-hostingYesNo
TranscriptionYesYes (as part of dubbing)
TranslationNoYes
Voice synthesisNoYes
Offline useYesNo
PricingFree (self-hosted)Paid subscription

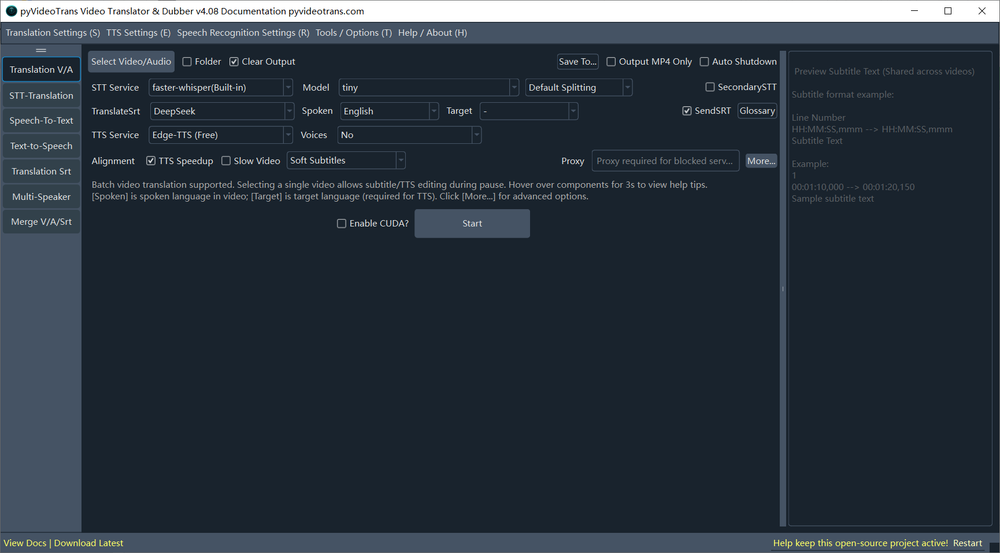
If you need full video translation and dubbing, stt alone is not a replacement for Rask AI. The related project pyVideoTrans (jianchang512/pyvideotrans) pairs stt's speech recognition with translation and TTS synthesis to approximate that workflow. For pure transcription with no dubbing requirement, stt provides equivalent output to Rask AI's speech recognition step at no per-minute cost.

install · quick start

Quick start#

bash
Source code deployment requires Python 3.9 to 3.11 and ffmpeg installed on the system.

```bash
git clone [email protected]:jianchang512/stt.git .
python -m venv venv
source ./venv/bin/activate
pip install -r requirements.txt
python start.py
```
tech stack · detected from GitHub

What it's built on#

Languages
Python
Frameworks
Flask
frequently asked

FAQ#

Is stt free to use?

Yes. stt is GPL-3.0 licensed open source software with no usage fees. You download and run it on your own hardware at no cost. The only expense is the server or machine it runs on, and the tiny or small model is usable on modest CPU-only hardware.

Can stt replace the OpenAI Whisper API?

Yes, for local or server-side use. stt exposes an OpenAI-compatible /v1 endpoint at http://127.0.0.1:9977/v1 that accepts the same request format as OpenAI's audio transcriptions API. Change the base_url in your OpenAI client to point at stt and the rest of the code stays the same. Supported response formats are text, SRT, and JSON.

What model size should I use for best accuracy?

large-v3 gives the highest accuracy but requires an Nvidia GPU with 8GB or more VRAM. For CPU-only machines, medium is the practical ceiling before memory issues arise. tiny is the built-in default and works well for quick drafts or testing. Download additional model packages from the GitHub Releases page and place the extracted folder inside the models/ directory.

Does stt support GPU acceleration?

Yes, for Nvidia GPUs with CUDA. Install CUDA Toolkit and cuDNN first, then edit set.ini to set devtype=cuda and restart the app. GPU acceleration substantially speeds up inference on larger models and longer files. Machines without an Nvidia GPU, or without properly configured CUDA, run on CPU automatically.

What languages does stt support?

stt supports 14 languages: Chinese, English, French, German, Japanese, Korean, Russian, Spanish, Thai, Italian, Portuguese, Vietnamese, Arabic, and Turkish. Select the language per request in the browser UI or pass it as the language parameter in the API call.

also worth a look

Similar open-source tools#

YouDub-webui

Alternative toRask AI

Self-hosted AI video dubbing: YouTube to Chinese, Bilibili to English

  • 5,703 GitHub stars
  • Apache-2.0Licence Apache-2.0

pyvideotrans

Alternative toRask AI

Open source video translation with AI dubbing and voice cloning

  • 19,477 GitHub stars
  • GPL-3.0Licence GPL-3.0

OpenCreator

Alternative toHeyGen

Local AI workspace for video, image, voice, and translation

  • 13,637 GitHub stars
  • Apache-2.0Licence Apache-2.0

Openspline

Alternative toHeyGen LiveAvatar

Talking-avatar SDK for voice AI agents, MIT-licensed, Python and Node.

  • 261 GitHub stars
  • MITLicence MIT

video-use

Alternative toDescript

Edit videos by chatting with Claude Code, not clicking menus

  • 29,418 GitHub stars
  • MITLicence MIT

MoneyPrinterTurbo

Alternative toInVideo AI

AI-powered short video generation from topic to publish

  • 133,408 GitHub stars
  • MITLicence MIT
by category

Open source tools in these categories#

404

AI & Machine Learning

freeCodeCamp, OpenClaw, REA (Reverse Engineer Anything)
461

Developer Tools

REA (Reverse Engineer Anything), superpowers, Skills for Real Engineers
Hostinger

Run stt on your own server

Self-host stt on a Hostinger VPS.

Deploy on Hostinger

Featured

Inbox Zero

Alternative toSuperhuman

AI email assistant that drafts replies and clears your inbox

  • 12,712 GitHub stars
  • AGPL-3.0Licence AGPL-3.0
  • #Email

rakazo

Alternative toGrok Bot

AI teammates you own: your keys, your model, your machine.

  • 4,904 GitHub stars
  • Apache-2.0Licence Apache-2.0
  • #AI Agents

Omnara

Alternative toCClaude Managed Agents

Open-source agent deployment API. Self-host or use Omnara Cloud.

  • 2,957 GitHub stars
  • Apache-2.0Licence Apache-2.0
  • #AI Agents
Feature your project

New open source projects by email

The projects we add and every new guide. Free, unsubscribe any time.

Find open source alternatives to paid software

/
  • Claude Code to OpenCode
  • Jira to Windshift
  • Notion to AppFlowy
  • Slack to Mattermost
  • Linear to GitLab
  • Wispr Flow to Handy
  • CapCut to Concat
  • Grok Bot to rakazo
  • Superhuman to Inbox Zero
  • Airtable to AITable
  • Muse to OpenClaw
  • GitHub Copilot to Cline
  • Datadog to Netdata
  • Microsoft Teams to Rocket.Chat
  • Pinecone to Qdrant
  • Zapier to n8n
  • Devin AI to OpenHands
  • Firebase to Supabase
  • 1Password to KeePassXC
  • Confluence to Docmost
  • Contentful to Strapi
  • Adobe Premiere Pro to Shotcut
  • ChatGPT to AnythingLLM
  • LangSmith to Langfuse