Open Source Alternatives
  • Alternatives
  • Categories
    Categories by size882 projects
    • Developer Tools461
    • AI & Machine Learning404
    • Web Development196
    • Business & Productivity191
    • Communication & Collaboration126
    • Security & Monitoring126
    • IT Management123
    • Product & Project Management106
    • Cloud & Hosting105
    • Data & Analytics104
    Browse all 21 categoriesLLMOps & AI Tooling, Design & Creative and 9 more
  • Blog
  • Advertise
SearchNotion, Slack, password manager.../
Submit
Open Source Alternatives
  • Alternatives
    • Developer Tools461
    • AI & Machine Learning404
    • Web Development196
    • Business & Productivity191
    • Communication & Collaboration126
    • Security & Monitoring126
    • Browse all 21 categories
  • Blog
  • Advertise
Submit your project

New open source projects by email

The projects we add and every new guide. Free, unsubscribe any time.

Open Source Alternatives LogoOpen Source Alternatives

Handpicked Open Source Alternatives to Paid Softwares

Product

  • Categories
  • Tag
  • Advertise

Resources

  • Blog
  • Collection
  • Submit

Company

  • Privacy Policy
  • Terms of Service
  • Refund Policy
  • Sitemap

Alternatives

  • Claude Code
  • Jira
  • Notion
  • Slack
  • Linear
  • Wispr Flow
  • All alternatives
© 2026 Open Source Alternatives. All rights reserved.
Open SourceAlternatives
Home/Categories/AI & Machine Learning/magnitude
icon of magnitude

magnitude

Open source alternative to LM Studio

  • 7.2K stars
  • Apache-2.0
  • Active this week
  • Last commit 2 days ago

Last verified Oct 20, 2026

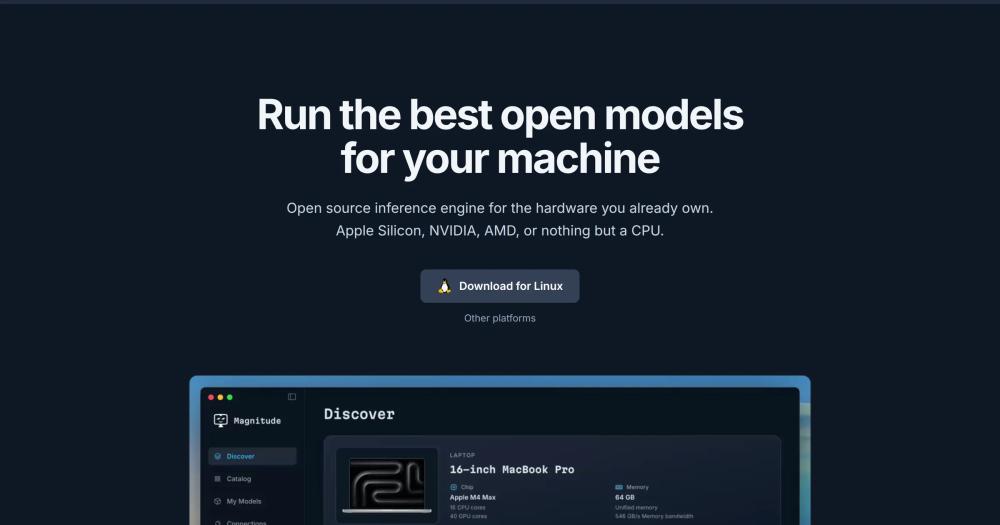
Run local LLM inference for AI agents with hardware-aware model selection, speculative decoding, and offline-first privacy.

Visit websiteGitHub7.2K starsDeploy on Hostinger
image of magnitude
TL;DR

magnitude is an open source inference server that profiles your hardware, picks the best-fit local models, and runs them in the background for the AI agents you already use. It replaces per-token cloud API billing for agent workloads by running inference locally with no API keys, no rate limits, and no data leaving your machine. Licensed under Apache 2.0, it supports macOS and Linux (Windows via WSL). Best for developers using coding agents who want private, offline inference without ongoing cloud costs.

Read the full breakdownHide the full breakdownWho it is for, how it works, trade-offs, the quick start and the FAQ
who it's for

Who magnitude is for#

Developers using AI coding agents to cut cloud API costs

Engineers running Claude Code, Cline, or OpenCode on agentic tasks pay token costs that accumulate across a full workday of multi-step coding sessions. Magnitude routes those calls to a local model, removing the per-token cost entirely while keeping the existing agent workflow intact.

Skip if:

Your machine has under 4GB of free RAM, or your work requires frontier model quality (complex reasoning, advanced math) that small local models cannot match. For those workloads, cloud APIs remain the better fit.

Engineers working with proprietary or compliance-sensitive code

Developers who want AI agent assistance on private codebases, unreleased products, or compliance-sensitive data without sending prompts to a third-party API. Magnitude keeps all prompts and context local with no cloud relay at any point in the inference path.

Skip if:

Your work environment restricts installation of local server software on work machines. In that case, a managed cloud deployment would be needed, which Magnitude does not provide as a hosted option.

Developers building or debugging in offline or restricted-network environments

Once a model is downloaded, Magnitude runs with no internet connection. Developers working without reliable internet, while traveling, or in restricted-network facilities can continue using agent-assisted coding without cloud access.

Skip if:

You need to download new models or update the catalog during the offline period. The initial CLI install and model download both require an internet connection.

Open source contributors building without cloud API budgets

Solo developers and open source maintainers who want AI agent assistance but cannot justify ongoing cloud API costs. Magnitude provides a free-to-run local inference path with Apache 2.0 licensing and no ongoing fees after the initial setup.

Skip if:

You need frontier model quality for daily work. Local models on consumer hardware will not match the output quality of GPT-4 or Claude Opus on complex tasks; if that bar is required, cloud APIs remain the practical choice.

the problem

The problem it solves#

Running local models for AI agent workloads is harder than it should be. Your agent does not know your hardware: it cannot tell which model quantization fits your RAM, what inference speed to expect, or how to configure the runtime for concurrent agent calls. Setting up a local inference stack manually means guessing at quant levels, tuning concurrency by trial and error, and writing harness configuration by hand.

The result is that most developers default to cloud LLM APIs and accept the costs. Token fees accumulate fast on agentic tasks that make dozens of LLM calls per session. Cloud APIs also mean prompts, context windows, and files leave your machine, which is a privacy concern for developers working with proprietary or sensitive code.

how magnitude solves it

How it solves it#

Hardware profiling and model recommendations

Magnitude profiles your chip, memory, and bandwidth, then computes the best-fit models from its curated catalog with estimated tokens per second for your specific hardware. You pick from a ranked list built for what will actually run fast on your machine, rather than guessing at quantization levels manually.

Agent-first onboarding via a single prompt

Send one prompt to your agent and it walks through the full setup: installs the Magnitude CLI, profiles your hardware, downloads the chosen model, and writes the harness configuration automatically. Compatible with Pi, OpenCode, Hermes, OpenClaw, Codex, Claude Code, Oh My Pi, and Cline, or use the built-in harness.

Just-in-time model loading and memory management

Models load when your agent needs them and unload automatically when idle or when memory gets tight. This keeps RAM available on machines where you run other workloads alongside the inference server, without requiring you to manage model lifecycle manually.

End-to-end inference tuning

Speculative decoding and concurrency are configured automatically for your hardware and selected model. Magnitude sets these based on the hardware profile it collects, removing the need to tune inference parameters by hand before agent workloads perform reliably.

Fully offline after initial setup

Once Magnitude and your chosen model are downloaded, no internet connection is required for inference. Prompts, context windows, and files stay on your machine and never reach any external server, making it suitable for air-gapped or network-restricted environments.

Custom GGUF model support

You can import compatible GGUF models from Hugging Face outside the built-in catalog. This lets you use specialized or fine-tuned models not included in the default recommendations, while still benefiting from Magnitude's runtime management and agent harness integration.

strengths · trade-offs

Strengths and trade-offs#

Strengths

  • Zero token costs for agent workloadsAgentic tasks typically make dozens of LLM calls per session. Routing those calls through Magnitude eliminates per-token API fees entirely. There are no API keys to manage, no rate limits to hit, and no cloud billing to monitor once the initial setup is complete.
  • Hardware-aware inference, not guessworkSetting up a local inference stack manually requires guessing at quant levels, which risks OOM errors or poor throughput. Magnitude measures your machine first and produces a catalog with concrete tok/s estimates, making model selection a data-driven step rather than trial and error.
  • Full data privacy with no cloud relayPrompts, files, and model weights stay on your machine throughout the inference path. For developers working with proprietary code, private documents, or compliance-sensitive data, this is the data-privacy guarantee that cloud APIs cannot offer.
  • Works with major agent harnesses out of the boxMagnitude integrates directly with Claude Code, Cline, OpenCode, Hermes, Pi, OpenClaw, Codex, and Oh My Pi. The onboarding flow configures the harness connection automatically, so switching a running agent from a cloud API to local inference is a setup step, not a code change.

Trade-offs

  • -Model quality is bounded by available RAMThe models Magnitude can run are constrained by your hardware. On machines with limited RAM, only smaller quantized models fit, which produce noticeably weaker output than frontier cloud models on complex reasoning tasks. More available memory is the prerequisite for larger, more capable models.
  • -macOS and Linux only; Windows requires WSLNative Windows support is not available. Windows users must have WSL installed and configured before running Magnitude. This adds a prerequisite step for developers on Windows who have not already set up WSL, and WSL carries some performance overhead compared to native Linux.
  • -Young project with a growing model catalogMagnitude was created in June 2026 and its curated catalog is still expanding. Models not yet in the catalog must be imported manually as GGUF files from Hugging Face. Users who need a specific model outside the catalog will need to handle that import themselves.
versus alternatives

magnitude vs alternatives#

Cloud LLM APIs

Most AI agents default to cloud LLM APIs because setup is straightforward: add an API key and start calling. Providers like OpenAI and Anthropic offer capable models through managed APIs with no infrastructure to run. Magnitude takes the opposite approach: local inference, on your hardware, with models selected and tuned for your machine. It is an open source alternative to paid API services for developers who want zero token costs and full data privacy.

MagnitudeCloud LLM APIs
LicenseApache 2.0Proprietary (API access)
Inference costFree (hardware you already own)Per-token billing
Data privacyFully local, no cloud relayPrompts sent to third-party servers
Model quality ceilingBounded by local hardwareFrontier models available
Rate limitsNoneTier-dependent
Works offlineYes (after model download)No
Setup effortCLI install plus hardware profileAPI key only
Agent harness supportPi, OpenCode, Hermes, Cline, Claude Code, and moreAny API-compatible agent

Magnitude is the better choice when cost and privacy are the primary constraints. Agentic tasks make many LLM calls per session; billing those through a cloud API accumulates fast across a workday, while local inference costs only the hardware you already own. For teams handling proprietary code or compliance-sensitive data who cannot send prompts to a third-party server, Magnitude is the practical path to agent-assisted development without cloud exposure.

When Cloud APIs Fit Better

Cloud APIs remain the stronger choice when you need frontier model quality that local hardware cannot deliver, when you need managed uptime without infrastructure to operate, or when your hardware is too constrained to load a useful model. On machines with limited RAM, the quality gap between local and frontier models is substantial enough that cloud APIs are still worth the per-token cost for complex reasoning tasks.

install · quick start

Quick start#

bash
Install the Magnitude CLI via npm on macOS or Linux (Windows requires WSL), then run the guided setup to profile your hardware and select a local model.
```bash
npm install -g @magnitudedev/cli
magnitude setup
```
tech stack · detected from GitHub

What it's built on#

Languages
CC++PythonRustTypeScript
frequently asked

FAQ#

Does Magnitude require specific hardware or a minimum spec?

No minimum specification is required. Magnitude profiles your actual hardware and recommends the best-fit models for what you have. Machines with more RAM can run larger and more capable models, but Magnitude finds something workable for most modern hardware. More available memory is the primary lever for improving model quality.

Does Magnitude send any data to the cloud?

No. Prompts, files, and model weights stay on your machine. Once Magnitude and a model are downloaded, inference runs entirely offline with no external network calls during operation.

Which AI agent harnesses work with Magnitude?

Pi, OpenCode, Hermes, OpenClaw, Codex, Claude Code, Oh My Pi, and Cline. During onboarding, Magnitude writes the harness configuration automatically, connecting your agent to the local model you select. A built-in harness is also available if you are not using one of those tools.

Can I use models not in the Magnitude catalog?

Yes. You can download compatible GGUF models from Hugging Face and use them with Magnitude. The catalog provides curated recommendations tuned to your hardware, but it is not a closed list. Custom models are loaded and managed the same way as catalog models.

Does Magnitude work on Windows?

Not natively. Magnitude supports macOS and Linux. Windows users can run it through WSL (Windows Subsystem for Linux). WSL must be installed and configured before running Magnitude on Windows.

also worth a look

Similar open-source tools#

LocalAI

Alternative toOpenAI API

Self-hosted AI runtime: any model, any modality, any hardware.

  • 49,798 GitHub stars
  • MITLicence MIT

llama-swap

Alternative toLM Studio

Hot-swap AI models on your local inference server

  • 6,013 GitHub stars
  • MITLicence MIT

omlx

Alternative toLM Studio

Fast LLM inference for Apple Silicon with persistent SSD KV caching

  • 22,964 GitHub stars
  • Apache-2.0Licence Apache-2.0

Ollama

Alternative toLM Studio

Run large language models locally on Mac, Linux, or Windows

  • 184,070 GitHub stars
  • MITLicence MIT

Hermes Agent

Featured

Alternative toGrok Bot

Self-hosted AI agent: persistent memory, multi-channel chat, model choice.

  • 255,514 GitHub stars
  • MITLicence MIT

Vllm

Alternative toTogether AI

High-throughput LLM inference server with OpenAI-compatible API

  • 94,441 GitHub stars
  • Apache-2.0Licence Apache-2.0
by category

Open source tools in these categories#

404

AI & Machine Learning

freeCodeCamp, OpenClaw, REA (Reverse Engineer Anything)
463

Developer Tools

REA (Reverse Engineer Anything), superpowers, Skills for Real Engineers
101

LLMOps & AI Tooling

Hermes Agent, OpenCode, MarkItDown
Hostinger

Run magnitude on your own server

Self-host magnitude on a Hostinger VPS.

Deploy on Hostinger

Featured

Omnara

Alternative toCClaude Managed Agents

Open-source agent deployment API. Self-host or use Omnara Cloud.

  • 2,957 GitHub stars
  • Apache-2.0Licence Apache-2.0
  • #AI Agents

rakazo

Alternative toGrok Bot

AI teammates you own: your keys, your model, your machine.

  • 4,904 GitHub stars
  • Apache-2.0Licence Apache-2.0
  • #AI Agents

Inbox Zero

Alternative toSuperhuman

AI email assistant that drafts replies and clears your inbox

  • 12,712 GitHub stars
  • AGPL-3.0Licence AGPL-3.0
  • #Email
Feature your project

New open source projects by email

The projects we add and every new guide. Free, unsubscribe any time.

Find open source alternatives to paid software

/
  • Claude Code to OpenCode
  • Jira to Windshift
  • Notion to AppFlowy
  • Slack to Mattermost
  • Linear to GitLab
  • Wispr Flow to Handy
  • CapCut to Concat
  • Grok Bot to rakazo
  • Superhuman to Inbox Zero
  • Airtable to AITable
  • Muse to OpenClaw
  • GitHub Copilot to Cline
  • Datadog to Netdata
  • Microsoft Teams to Rocket.Chat
  • Pinecone to Qdrant
  • Zapier to n8n
  • Devin AI to OpenHands
  • Firebase to Supabase
  • 1Password to KeePassXC
  • Confluence to Docmost
  • Contentful to Strapi
  • Adobe Premiere Pro to Shotcut
  • ChatGPT to AnythingLLM
  • LangSmith to Langfuse