
Developers prototyping AI features locally
Ollama shortens the loop between prompt changes and application behavior.
Skip if:
you need a managed production SLA from day one.

Open source alternative to LM Studio, Hugging Face Inference Endpoints, Google Cloud Vertex AI and Databricks
Last verified
Ollama runs large language models locally on your own hardware with a simple CLI and an OpenAI-compatible API. MIT licensed, supports Mac, Linux, and Windows.
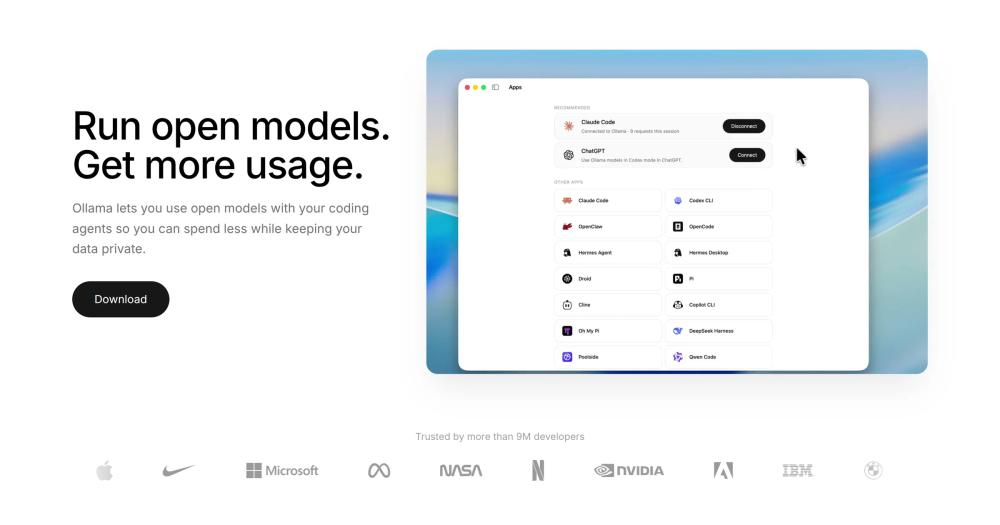
Ollama shortens the loop between prompt changes and application behavior.
you need a managed production SLA from day one.
local execution keeps early tests off external inference APIs.
your workloads require models too large for your available hardware.
the model library makes side-by-side testing practical.
you need hosted collaboration and billing controls.
Hosted inference APIs are convenient, but they move prompts, files, and application traffic through external providers. That creates privacy questions for sensitive data, network dependency for local development, and recurring inference costs for experiments that could run on a workstation or internal server.
Developers also lose speed when every model test requires account setup, remote quotas, and provider-specific APIs. A local model runner makes the feedback loop shorter: pull a model, run it, and connect an app against a local endpoint before deciding whether production needs managed infrastructure.
One-command model runs through the Ollama CLI, including popular families such as Llama, Qwen, Gemma, DeepSeek, Mistral, and embedding models.
Local API support lets applications connect to models running on a developer machine or internal server.
Model library includes multiple parameter sizes, so teams can choose small laptop-friendly models or larger GPU-backed models.
Official installers cover macOS, Linux, Windows, and Docker for local or server deployment.
MIT license gives developers room to embed Ollama in internal workflows and commercial products.
curl -fsSL https://ollama.com/install.sh | sh
ollama run llama3.1Yes. Ollama is MIT licensed and free to install locally. Your real cost is the hardware needed to run the models you choose.
Yes, after you download a model, Ollama can run it locally without calling a hosted inference API. You still need internet access to pull new models or updates.
Ollama can run smaller models on many modern laptops, but larger models need more RAM and GPU memory. Pick model sizes based on the machine you plan to use.

Alternative to Databricks
Open lab for training foundation models together

Alternative to NotebookLM
Self-host private AI research notebooks

Alternative to Together AI
Train LLMs locally without code using a browser-based interface

Alternative to OpenAI API
Full transparency LLM: open weights, training code, and data

Alternative toDatabricks
Apache 2.0 LLM fine-tuning toolkit for Llama and Mistral on GPU

Alternative toOpenAI API
Self-hosted AI runtime: any model, any modality, any hardware.
Run Ollama on your own server
Hostinger sets Ollama up as a one-click app on a VPS.
Deploy on HostingerFeatured

Alternative to Superhuman
AI email assistant that drafts replies and clears your inbox

Alternative toClaude Managed Agents
Open-source agent deployment API. Self-host or use Omnara Cloud.

Alternative to Grok Bot
AI teammates you own: your keys, your model, your machine.
The projects we add and every new guide. Free, unsubscribe any time.
 Claude Code to
 OpenCode
 Jira to
 Windshift
 Notion to
 AppFlowy
 Slack to
 Mattermost
 Linear to
 GitLab
 Wispr Flow to
 Handy
 CapCut to
 Concat
 Grok Bot to
 rakazo
 Superhuman to
 Inbox Zero
 Airtable to
 AITable
 Muse to
 OpenClaw
 GitHub Copilot to
 Cline
 Datadog to
 Netdata
 Microsoft Teams to
 Rocket.Chat
 Pinecone to
 Qdrant
 Zapier to
 n8n
 Devin AI to
 OpenHands
 Firebase to
 Supabase
 1Password to
 KeePassXCConfluence to
 Docmost
 Contentful to
 Strapi
 Adobe Premiere Pro to
 Shotcut
 ChatGPT to
 AnythingLLM
 LangSmith to
 Langfuse


