
Open Source Alternatives
  • Alternatives
  • Categories
    Categories by size882 projects
    • Developer Tools461
    • AI & Machine Learning404
    • Web Development196
    • Business & Productivity191
    • Communication & Collaboration126
    • Security & Monitoring126
    • IT Management123
    • Product & Project Management106
    • Cloud & Hosting105
    • Data & Analytics104
    Browse all 21 categoriesLLMOps & AI Tooling, Design & Creative and 9 more
  • Blog
  • Advertise
SearchNotion, Slack, password manager.../
Submit
Open Source Alternatives
  • Alternatives
    • Developer Tools461
    • AI & Machine Learning404
    • Web Development196
    • Business & Productivity191
    • Communication & Collaboration126
    • Security & Monitoring126
    • Browse all 21 categories
  • Blog
  • Advertise
Submit your project

New open source projects by email

The projects we add and every new guide. Free, unsubscribe any time.

Open Source Alternatives LogoOpen Source Alternatives

Handpicked Open Source Alternatives to Paid Softwares

Product

  • Categories
  • Tag
  • Advertise

Resources

  • Blog
  • Collection
  • Submit

Company

  • Privacy Policy
  • Terms of Service
  • Refund Policy
  • Sitemap

Alternatives

  • Claude Code
  • Jira
  • Notion
  • Slack
  • Linear
  • Wispr Flow
  • All alternatives
© 2026 Open Source Alternatives. All rights reserved.
Open SourceAlternatives
Home/Categories/AI & Machine Learning/Kev
icon of kev

Kev

Open source alternative to Jev

  • 9.3K stars
  • Apache-2.0
  • Active this week
  • Last commit 5 days ago

Last verified Oct 19, 2026

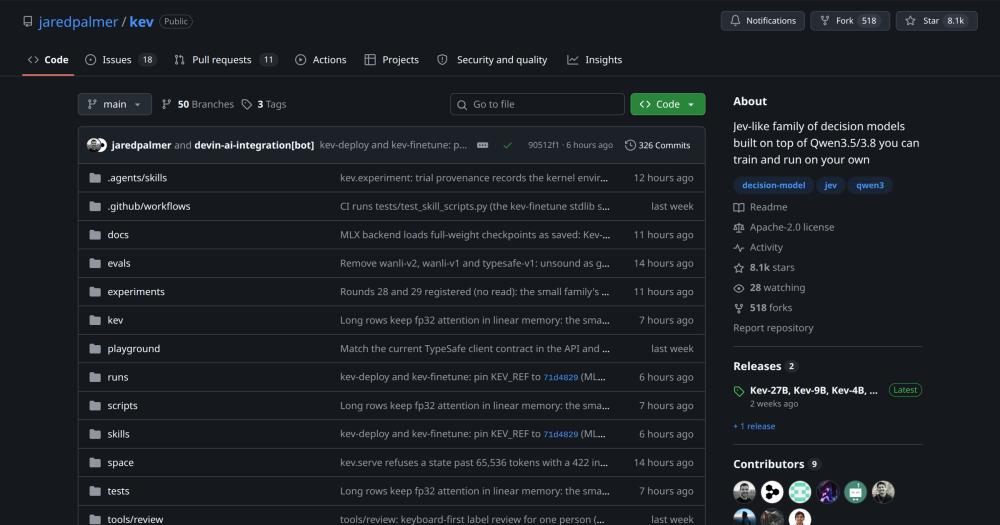
Run Jev-compatible decision models on your own hardware or Modal, with four sizes from a 0.8B laptop model to a 27B datacenter GPU. Apache-2.0.

Visit websiteGitHub9.3K stars
image of kev
TL;DR

Kev is a family of small open source decision models (0.8B to 27B parameters) that route tickets, flag escalations, and score sentiment without sending data to a third-party API. It replaces Jev, TypeSafe's hosted decision model, with a self-hosted path that shares the same API contract and works with the existing TypeSafe Python SDK unchanged. Licensed Apache-2.0, deployable locally or on Modal. Best for engineering teams moving classification workloads off a hosted API.

Read the full breakdownHide the full breakdownWho it is for, how it works, trade-offs, the quick start and the FAQ
who it's for

Who Kev is for#

Customer support teams routing and scoring tickets

Kev handles department routing, urgency scoring, and escalation flagging in a single API call. Teams currently paying Jev's per-request fee for every incoming ticket can move classification to their own GPU or a Modal endpoint without changing the TypeSafe Python SDK calls in their code.

Skip if:

Your support volume is low enough that Jev's per-request cost is not a concern and you have no data-residency requirements. A hosted API with no infrastructure overhead is simpler at small scale.

ML engineers replacing a Jev dependency with a self-hosted model

Kev's API is a drop-in for TypeSafe's System One endpoint. Replacing Jev is a URL change in the client config. On most classification benchmarks, Kev-27B is within one point of Jev's accuracy, so migration risk is low for routing and entailment tasks.

Skip if:

Your pipeline relies on Jev's performance on hard knowledge questions. Kev-27B trails significantly on MMLU-Pro (0.675 vs 0.840), so knowledge-intensive classification should be tested before migrating.

Teams with proprietary data who need domain fine-tuning

Kev accepts labeled examples in the same format as the API request, with a label field added to each question. Fine-tuning from a released checkpoint with --init_from takes one or two epochs and costs about $1 on an H100 via Modal. The benchmark script reports accuracy per question type so you know which questions improved.

Skip if:

Your dataset has fewer than a few hundred labeled examples. On a 400-record dataset, accuracy gains were within measurement noise. You need at least around 1,000 examples to see reliable gains.

the problem

The problem it solves#

Structured classification tasks like ticket routing, escalation flagging, and sentiment scoring are cheap to run when you own the model but expensive when you pay per-request to a hosted API. Teams using Jev send every customer interaction to TypeSafe's servers, which creates data residency concerns for regulated industries and adds per-request costs that compound at scale.

The harder part is that hosted-only models cannot be adapted to domain-specific routing rules, your own escalation criteria, or languages not in the training data. When the pretrained model does not fit your categories well, your only option with a hosted API is better prompting; with a model you own, you can fine-tune on labeled examples from your own data and measure the improvement on a held-out set.

how Kev solves it

How it solves it#

Three question types in one request

Kev handles yes/no (noul), multiple-choice (choice), and rating (score) questions in a single API call. A ticket can be routed to a department, flagged for escalation, and scored for urgency in one round trip; questions share the input text but cannot read each other's answers.

Calibrated probabilities by default

Each checkpoint ships with a temperature fitted on held-out data, so Kev returns calibrated confidence values. At a 5% error budget on new-source data, Kev-4B, 9B, and 27B automate 0.52 to 0.69 of decisions; that threshold holds because the probabilities are measured on real data, not estimated.

Drop-in for the TypeSafe Python SDK

Kev's HTTP server exposes the same /v1/systemone endpoint as TypeSafe's System One API. Any code calling Jev through the TypeSafe Python SDK works against a local Kev server with a single base URL change. No wrapper, no schema migration, no adapter layer needed.

Four model sizes for different hardware

Kev-0.8B runs on any Apple Silicon Mac or a 4 GB GPU; Kev-4B is the recommended starting point for a 32 GB Mac, L40S, or H100; Kev-9B trades a small accuracy gain for more GPU memory; Kev-27B needs an 80 GB H100 or better. Accuracy scales with size: Kev-27B reaches 0.851 on new-source classification while Kev-0.8B reaches 0.648.

Fine-tuning on your own labels

A domain fine-tune updates the model to your specific routing categories, escalation rules, and language. On an example support workload, fine-tuning Kev-4B from 1,050 generated records moved accuracy from 67.7% to 73.6% and lifted automated decisions from 34% to 48% at a 5% error budget. A coding-agent skill runs the full loop on Modal for about $1.

Modal deployment with scale-to-zero

A three-command script deploys Kev-4B to Modal and produces an HTTPS endpoint behind an API key. The container scales to zero when idle, so an unused endpoint costs nothing. The first request after idle waits about 35 seconds for a container to start.

strengths · trade-offs

Strengths and trade-offs#

Strengths

  • Apache-2.0 with no commercial restrictionsEvery Kev checkpoint is Apache-2.0 licensed, which allows commercial self-hosting, fine-tuning, and redistribution without restrictions. Unlike Jev, which is a hosted-only proprietary API, you can run Kev inside your own network and keep all customer data on your infrastructure.
  • Accuracy within one point of Jev on routing tasksKev-27B scores 0.851 accuracy and 0.156 Brier score on new-source classification, compared to Jev's 0.857 accuracy and 0.211 Brier score. On eight of eleven benchmark categories Kev-27B matches or beats Jev. Kev-4B and 9B are within four points on classification tasks like routing and entailment.
  • Fine-tunable on domain dataReleased checkpoints accept short domain fine-tunes that improve accuracy on your specific task. On real consumer-finance complaints, one epoch on 5,219 labeled examples took Kev-4B from 0.804 to 0.904 accuracy on held-out data. Using --init_from preserves what the pretrained model knows while adding your domain on top.
  • Runs on Apple Silicon for local developmentKev-0.8B and Kev-4B run on Apple Silicon Macs via MLX with no cloud dependency. Kev-4B answers five questions about a short text in 721 ms on an M5, dropping to 136 ms on cache hits. This makes local development and debugging practical without renting GPU time.

Trade-offs

  • -Kev-27B requires an 80 GB GPUKev-27B ships as 51 GB of full weights and needs an 80 GB H100, H200, or B200 to run (or a 96-128 GB Mac, which was not tested at release). Unlike the 0.8B, 4B, and 9B models, it is not available as an adapter; the full checkpoint is Hub-only and too large for a GitHub release.
  • -Accuracy degrades on long documents for smaller modelsKev-0.8B, 4B, and 9B were trained mostly on inputs up to 384 tokens. They accept up to 65,536 tokens, but accuracy degrades on long documents. Kev-27B handles up to 32,768 training tokens and scores 0.874 on CUAD contracts, but its calibration becomes less reliable at longer lengths; the smaller models have no published long-document results.
  • -Modal cold start of about 35 secondsWhen a Modal-hosted Kev endpoint has been idle, the first request waits around 35 seconds for a container to start. This is acceptable for batch classification jobs or low-traffic workflows, but it rules out synchronous user-facing flows that need sub-second latency.
  • -Knowledge-question accuracy trails Jev on harder benchmarksOn MMLU-Pro, Kev-27B scores 0.675 against Jev's 0.840, a gap of 16.5 points. The gap is smaller on standard MMLU (0.90 for both) and on classification-shaped tasks. Teams whose workloads depend on general world knowledge or day-precision date arithmetic should test Kev on their own data before committing to a migration.
versus alternatives

Kev vs alternatives#

Kev vs Jev

Both models answer the same three question types (yes/no, multiple-choice, score) and share the TypeSafe Python SDK as their interface. The key difference is deployment: Jev is a hosted API with no self-hosting option, while Kev runs on your own hardware or a Modal endpoint.

FeatureKevJev
LicenseApache-2.0Proprietary
Self-hostingYesNo
Fine-tuningYesNo
Model sizes0.8B, 4B, 9B, 27BHosted only
New-source accuracy (27B)0.8510.857
New-source Brier score (27B)0.1560.211
MMLU-Pro accuracy (27B)0.6750.840

Kev is the better choice when you need data privacy, cost control on high-volume classification, or the ability to fine-tune on your own labels. Kev-27B's Brier score is lower than Jev's on new-source data (0.156 vs 0.211), meaning its probabilities are better calibrated even where overall accuracy is within a point.

Jev is still worth considering when you need its performance on hard knowledge questions (Kev-27B trails by 16.5 points on MMLU-Pro), when you have no GPU or Modal setup budget, or when zero-configuration hosting matters more than data control.

install · quick start

Quick start#

bash
Deploy a local Kev server with Python 3.12 or 3.13 and the uv package manager.
```bash
git clone https://github.com/jaredpalmer/kev.git && cd kev
uv sync --extra serve
uv run --extra serve python -m kev.serve --run jaredpalmer/kev-4b --port 8009
```
tech stack · detected from GitHub

What it's built on#

Languages
PythonTypeScript
Frameworks
FastAPINext.jsReact
frequently asked

FAQ#

Is Kev as accurate as Jev?

On new-source classification benchmarks, Kev-27B reaches 0.851 accuracy versus Jev's 0.857, a gap of less than one point. Kev-4B and 9B are within four points on routing, entailment, and science questions. The main accuracy gap is on hard knowledge benchmarks like MMLU-Pro, where Kev-27B scores 0.675 against Jev's 0.840. For support routing and structured classification, the gap is small enough that most teams will not notice it in production.

What hardware do I need to run Kev?

Kev-0.8B runs on any Apple Silicon Mac or a 4 GB GPU. Kev-4B needs a 32 GB Mac, an L40S, or an H100. Kev-9B fits the same GPUs as 4B. Kev-27B requires an 80 GB H100, H200, or B200, or a 96-128 GB Mac (untested at release). If you have no GPU, you can deploy to Modal with one script and pay only for actual inference time.

Can I fine-tune Kev on my own support data?

Yes. Kev accepts labeled examples in the same JSON format as the API, with a label field on each question. A coding-agent skill (npx skills add jaredpalmer/kev@kev-finetune) runs the full loop from labeling to deployment on Modal for about $1. On a real consumer-finance dataset, one epoch of fine-tuning on 5,219 examples took Kev-4B accuracy from 0.804 to 0.904 on held-out data. Gains below roughly 1,000 labeled records are often inside measurement noise.

Does the TypeSafe Python SDK work with Kev without code changes?

Yes. Kev's server exposes the same /v1/systemone endpoint as TypeSafe's System One API. Point your TypeSafeClient at http://127.0.0.1:8009 (or your Modal endpoint URL) and keep the rest of your code unchanged. The TypeSafe SDK is included when you run uv sync --extra serve.

Is there a hosted demo of Kev I can try before running it locally?

Yes. A Hugging Face Space at huggingface.co/spaces/jaredpalmer/kev runs Kev-4B and Kev-0.8B with nothing to install. For local use, Kev-0.8B runs on any Apple Silicon Mac with three commands from the README.

also worth a look

Similar open-source tools#

Laya

Alternative toJev

Multilingual decision engine for typed answers without text generation

  • 33,527 GitHub stars
  • Apache-2.0Licence Apache-2.0

Vela

Alternative toGoogle Maps

OpenStreetMap and Google data, no account, no Play Services

  • 2,060 GitHub stars
  • GPL-3.0Licence GPL-3.0

FckSignups

InCustomer Support

Open-source tools that work instantly, no signup required

  • 4,511 GitHub stars
  • GPL-3.0Licence GPL-3.0

fmt

InCustomer Support

Fast, type-safe C++ formatting that replaces printf and iostreams

  • 25,884 GitHub stars
  • MITLicence MIT

agency-agents

InAI & Machine Learning

Expert AI agent personalities for every workflow

  • 162,144 GitHub stars
  • MITLicence MIT

rakazo

Featured

Alternative toGrok Bot

AI teammates you own: your keys, your model, your machine.

  • 4,904 GitHub stars
  • Apache-2.0Licence Apache-2.0
by category

Open source tools in these categories#

404

AI & Machine Learning

freeCodeCamp, OpenClaw, REA (Reverse Engineer Anything)
29

Customer Support

agency-agents, iptv, Twenty
106

Product & Project Management

Gstack, freeCodeCamp, agency-agents

Featured

Inbox Zero

Alternative toSuperhuman

AI email assistant that drafts replies and clears your inbox

  • 12,712 GitHub stars
  • AGPL-3.0Licence AGPL-3.0
  • #Email

rakazo

Alternative toGrok Bot

AI teammates you own: your keys, your model, your machine.

  • 4,904 GitHub stars
  • Apache-2.0Licence Apache-2.0
  • #AI Agents

Omnara

Alternative toCClaude Managed Agents

Open-source agent deployment API. Self-host or use Omnara Cloud.

  • 2,957 GitHub stars
  • Apache-2.0Licence Apache-2.0
  • #AI Agents
Feature your project

New open source projects by email

The projects we add and every new guide. Free, unsubscribe any time.

Find open source alternatives to paid software

/
  • Claude Code to OpenCode
  • Jira to Windshift
  • Notion to AppFlowy
  • Slack to Mattermost
  • Linear to GitLab
  • Wispr Flow to Handy
  • CapCut to Concat
  • Grok Bot to rakazo
  • Superhuman to Inbox Zero
  • Airtable to AITable
  • Muse to OpenClaw
  • GitHub Copilot to Cline
  • Datadog to Netdata
  • Microsoft Teams to Rocket.Chat
  • Pinecone to Qdrant
  • Zapier to n8n
  • Devin AI to OpenHands
  • Firebase to Supabase
  • 1Password to KeePassXC
  • Confluence to Docmost
  • Contentful to Strapi
  • Adobe Premiere Pro to Shotcut
  • ChatGPT to AnythingLLM
  • LangSmith to Langfuse