
AI engineers building RAG pipelines
Firecrawl converts public pages into cleaner Markdown or JSON before embedding.
Skip if:
your data sources are already structured APIs.

Open source alternative to Apify, Bright Data and ScrapingBee
Last verified
Firecrawl is an open source web scraping API for AI that turns websites into clean markdown or structured JSON for LLM and RAG pipelines. AGPL-3.0.
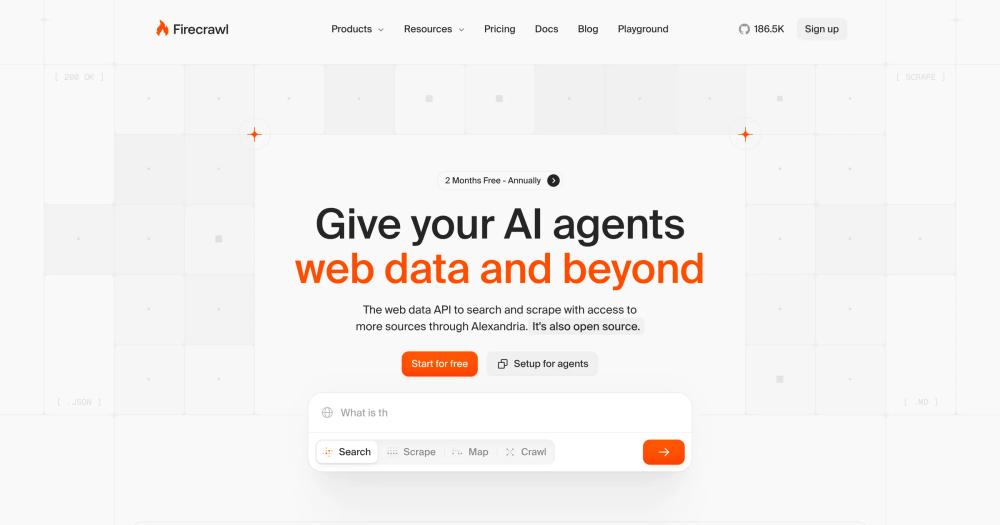
Firecrawl converts public pages into cleaner Markdown or JSON before embedding.
your data sources are already structured APIs.
MCP and skills integrations let assistants search, scrape, and extract during tool use.
browsing is not allowed in your agent environment.
crawl and scrape endpoints cover multi-page extraction.
target sites prohibit scraping or need formal data partnerships.
Web data extraction is brittle when teams build it from raw browser automation. Modern sites render content with JavaScript, block simple HTTP clients, and return noisy HTML that still needs cleaning before it works in RAG, search, or agent workflows.
Commercial scraping APIs solve some of that pain, but they can become expensive at volume and keep the extraction pipeline outside your infrastructure. AI teams need cleaner output, predictable formats, and a path to self-host when data privacy or cost control matters.
Scrape endpoint extracts page content as Markdown, HTML, screenshots, or structured JSON for downstream AI workflows.
Crawl and map endpoints discover and process multiple pages instead of forcing one-off URL scripts.
JavaScript rendering and dynamic-page handling reduce the need to maintain custom Playwright or Puppeteer workers.
SDKs cover Node.js, Python, Go, Rust, Ruby, PHP, Java, .NET, Elixir, and more.
MCP server and Firecrawl skills connect web extraction directly to AI coding and agent tools.
npx -y firecrawl-cli@latest init --all --browserFirecrawl can return clean Markdown, HTML, screenshots, links, metadata, or structured JSON depending on the endpoint and options. That makes it useful for RAG, search, extraction, and agent workflows.
Yes. Firecrawl is available as an open source repository under AGPL-3.0, and it also offers a hosted API. Self-hosting gives more infrastructure control but requires operating the scraping stack yourself.
Firecrawl focuses on AI-ready output and handles crawling, JavaScript rendering, cleaning, and structured extraction behind an API. A normal scraper usually leaves more browser automation and HTML cleanup to your team.

Alternative to Firecrawl
LLM-ready web crawling without API keys or rate limits

Alternative toFirecrawl
Give any AI agent internet access, free and local

Alternative to Browserbase
AI agent browser with shared Chrome state, zero cost
Alternative toFirecrawl
AI-native web scraping toolkit + MCP server

Alternative to Unstructured.io
Convert documents to clean markdown and JSON with open source AI.

Alternative to LlamaParse
Document parsing and ETL for LLMs, RAG pipelines, and AI agents.
Featured

Alternative to Superhuman
AI email assistant that drafts replies and clears your inbox

Alternative toClaude Managed Agents
Open-source agent deployment API. Self-host or use Omnara Cloud.

Alternative to Grok Bot
AI teammates you own: your keys, your model, your machine.
The projects we add and every new guide. Free, unsubscribe any time.
 Claude Code to
 OpenCode
 Jira to
 Windshift
 Notion to
 AppFlowy
 Slack to
 Mattermost
 Linear to
 GitLab
 Wispr Flow to
 Handy
 CapCut to
 Concat
 Grok Bot to
 rakazo
 Superhuman to
 Inbox Zero
 Airtable to
 AITable
 Muse to
 OpenClaw
 GitHub Copilot to
 Cline
 Datadog to
 Netdata
 Microsoft Teams to
 Rocket.Chat
 Pinecone to
 Qdrant
 Zapier to
 n8n
 Devin AI to
 OpenHands
 Firebase to
 Supabase
 1Password to
 KeePassXCConfluence to
 Docmost
 Contentful to
 Strapi
 Adobe Premiere Pro to
 Shotcut
 ChatGPT to
 AnythingLLM
 LangSmith to
 Langfuse


